
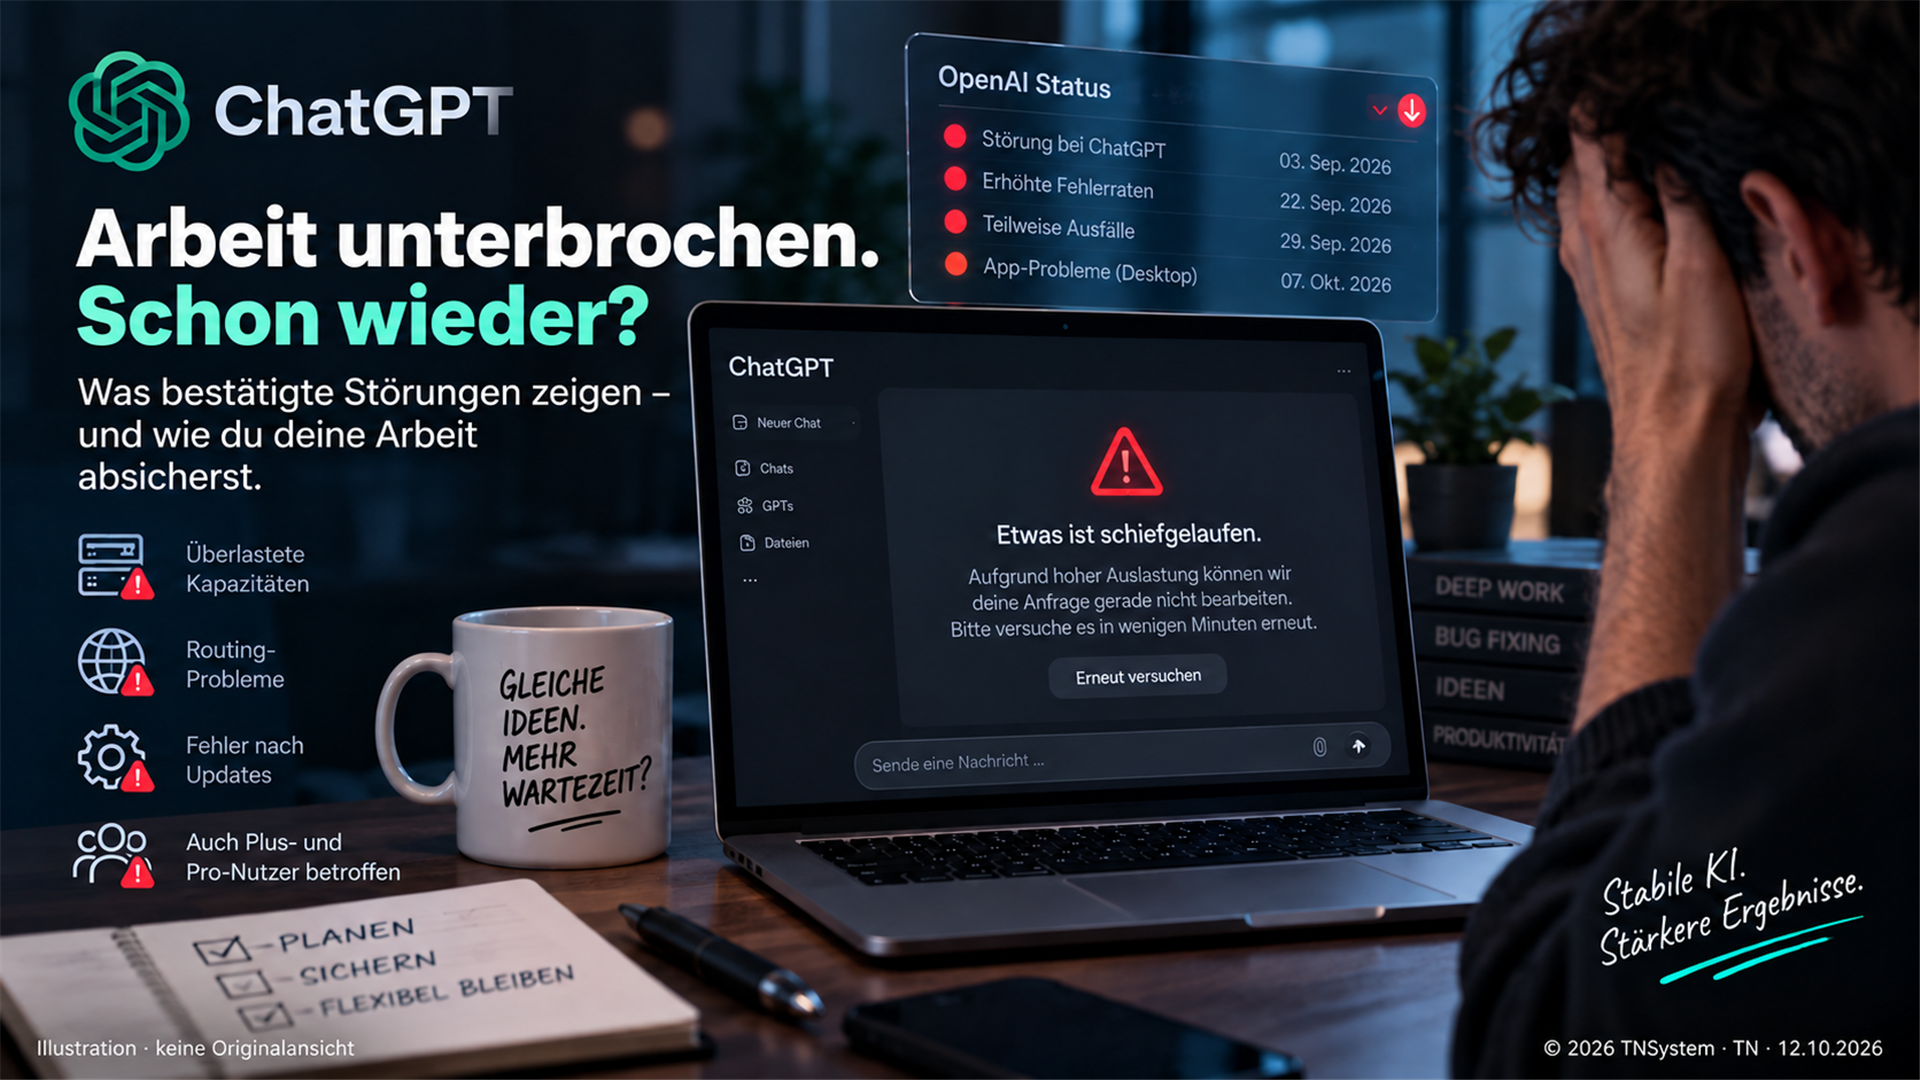
When work stops unexpectedly
The documents have been uploaded, the task explained and work is under way. Then the response stops. An error appears, the task is not completed or the conversation can suddenly no longer be opened.
Someone who tries ChatGPT occasionally may simply repeat the task later. Someone preparing customer documents, developing software or working towards publication may lose more than a few minutes.
These disruptions are not merely a subjective impression. OpenAI has documented problems that prevented tasks from starting, continuing or finishing. Several incident analyses explicitly identify overloaded resources and exhausted network capacity. [2][4]
Two questions still need to remain separate: Which interruptions are documented? And can a substantial increase in the overall frequency of errors be established?
There is clear evidence for the first question. The public information does not establish a universally applicable rate of increase for the second.
Current original evidence: a capacity message while using GPT-6.1 Sol
While working with GPT-6.1 Sol on 12 October 2026, I received the message shown below: “Selected model is at capacity. Please try a different model.”
This has happened to me more often recently, interrupting my work each time. When a task is already prepared, being told to try another model only helps so much.
I have not kept a complete measurement record. I can describe my experience, but it does not give me a general outage rate or a percentage increase.
I supplied the model name; it is not visible in the screenshot. The excerpt shows the message, not its internal cause or the number of affected users. It does not establish a general ChatGPT outage and should not automatically be assigned a particular API error code.
Another model may offer a way to continue if it is available and suitable for the task. That is not a guarantee. Before repeating an agent request, I would check completed actions and continue only unfinished work.

What OpenAI has documented
The following selection covers incidents from recent weeks. It is not a complete outage statistic. Affected features, groups of users and causes differ.
The information comes from OpenAI's incident notices and subsequent analyses. An incident does not mean that every user lost every feature throughout the period concerned.
Even this selection matters in practice: interruptions are not confined to free accounts or ordinary chat responses.
| Incident date | Documented disruption | Context |
|---|---|---|
| 31 August 2026 | Some ChatGPT Work tasks could not start or continue; responses were delayed. | OpenAI identifies overloaded shared network and computing resources. [2] |
| 3 September 2026 | Errors accessing ChatGPT and Codex, including some sign-in and account creation problems. | A routing change was processed incorrectly and prevented requests from reaching services. [3] |
| 22 September 2026 | Elevated error rates in ChatGPT Work across several paid plans. | The report names Plus, Pro, Business, Enterprise and Education. [5] |
| 23 and 30 September 2026 | Elevated conversation error rates for Plus and Pro users. | Two separate incidents, both subsequently marked resolved. [5] |
| 29 September 2026 | Failed requests, sign-in problems and unfinished tasks in ChatGPT, Codex and the API. | A feature rollout generated excessive internal network traffic. [4] |
| 7 October 2026 | An affected desktop app version could not create new ChatGPT Work conversations. | OpenAI released corrected versions for Linux, macOS and Windows. [6] |
Are errors actually becoming more frequent?
The public reports establish repeated disruptions close together. They do not directly show how much the probability of an error has increased for an individual user.
OpenAI states that availability figures are aggregated across plans, models and error types. Individual experience may differ according to the account and feature used. [1]
The history has another complication: later updates can place older incidents under a later date. The incident of 29 September, for example, also has a final update dated 6 October. Counting only the date groups in the overview can therefore misattribute when an incident occurred. [1][4]
A reliable trend comparison would need equal periods, equivalent features and consistent counting rules, ideally including the extent and duration of actual disruption.
The supportable conclusion is that repeated, work-relevant disruptions are documented. A blanket statement such as “ChatGPT now fails twice as often” would not be adequately supported by this research.
That does not diminish the experience of someone whose work has repeatedly stopped. It prevents personal impact from being confused with an overall service statistic.
Capacity problems are real—but not always caused by too many users
Capacity problems often suggest too few computers for too many requests. The published incident analyses present a more detailed picture.
31 August: A code change increased the load
According to OpenAI, a code change increased demand on the systems supporting ChatGPT Work. Background activity generated more network connections. Combined with normal usage, this exceeded available network capacity; memory pressure and retries intensified the overload.
The company describes an incident window of about five hours and thirteen minutes. Individual users were not necessarily affected throughout that period. Mitigation included temporarily limiting new tasks and adding capacity. [2]
This documents a capacity bottleneck, but not simply “too many paying customers”. The explanation involves software changes, background load and infrastructure limits together.
3 September: Available services were not reached correctly
For the incident of 3 September 2026, OpenAI identifies an incorrectly interpreted routing configuration. Requests stopped reaching services that were otherwise available.
Returning traffic then caused additional overload during recovery. According to the analysis, the broad disruption was mitigated after about 37 minutes. [3]
A service can therefore appear unavailable without all computing capacity simply being exhausted. Internal request distribution must work reliably too.
29 September: A new feature exhausted connection capacity
A feature rollout on 29 September 2026 triggered repeated background checks. These opened numerous internal connections. Failed checks led to further attempts until shared connection capacity was exhausted.
OpenAI reversed the triggering change. According to its analysis, most customer-facing impact was mitigated within about 30 minutes, although residual disruption lasted longer. [4]
More hardware alone will not prevent every interruption. Changes, retry mechanisms and demands on shared services also need to be controlled.
These reports are the provider's explanations. They do not replace an independent technical audit of its entire infrastructure.
What users describe online
Public user reports also illustrate how differently problems can appear in everyday work.
In an OpenAI developer community discussion beginning on 28 September 2026, users describe conversation history failing to load completely. Older conversations could sometimes still be found through search but were not reliably visible in the sidebar. One participant reported improvement on 5 October; another reported the problem returning on 6 October. [7]
A separate report on 6 October describes problems processing attached images, text files and PDFs in both the desktop application and browser. Support asked where the error occurred and suggested comparison checks. [7]
These posts are neither a representative survey nor evidence of a common cause. They help explain why an interruption does not necessarily stop affecting someone as soon as the next response succeeds.
Temporarily invisible history should not automatically be described as permanent data loss. In the discussion concerned, older conversations remained at least partly searchable.
Why a paid account does not mean complete protection against outages
OpenAI advertises Plus with priority access during high demand and fewer interruptions. Its help article also states that Plus can have usage limits that vary with system conditions. Both statements were present when checked on 12 October 2026. [8]
The official incidents of 22, 23 and 30 September also demonstrate that paid plans were affected in practice. [5]
Priority access is not the same as an application that works under every circumstance.
Nevertheless, I find higher expectations of a paid professional tool understandable. Someone organising work around it needs reliable delivery as well as capable models.
A higher plan would not automatically be my answer to recurring errors. First I would distinguish an exhausted allowance from a technical incident. A different allowance does not repair a fault in a shared application.
Different error messages mean different things
It is useful to distinguish three situations.
A usage limit restricts an account's or service's permitted use. A capacity bottleneck means that available resources temporarily cannot process a request. A connection or application error may have a different cause again.
OpenAI's API documentation distinguishes usage limits, internal server errors and the temporary model overload identified by 503 / server_is_overloaded. These are API descriptions, not a direct translation of every ChatGPT interface message. [10]
The general ChatGPT message “Something went wrong” is not specific. OpenAI lists temporary server problems and local factors such as browser extensions or network settings as possible causes. [9]
I would therefore neither blame every error on my computer nor treat every interruption as proven provider overload.
What was reported when the research was checked
When checked on 12 October 2026, the status page showed an ongoing notice about delayed cost data in the Compliance API. OpenAI explicitly stated that ChatGPT usage and API Platform requests were not affected. [13]
That notice is not evidence of a general ChatGPT outage at the time of checking. Equally, a status page cannot rule out other problems affecting individual accounts.
Read a status notice alongside the feature it describes—not merely its colour or headline.
How to handle interruptions more effectively
Fixing a server-side incident is the provider's responsibility. Users can still reduce the risk that one interruption undermines an entire piece of work.
Save intermediate results outside the conversation
For longer tasks, I would not leave all progress exclusively inside a chat. Accepted text, created files and important decisions should also go into the project's own storage.
A substantial task can be divided into assessable stages: foundations, draft and review. An interruption then need not require repeating everything.
A short handover note helps: What is complete? Which files are authoritative? What remains open?
That is not a repair for an outage. It is a precaution against unnecessary repeated work.
Narrow the issue before changing the local environment
For stuck responses, OpenAI recommends checking service status, trying a new conversation and comparing another browser, device or network. An up-to-date application or fresh browser profile may also help isolate interface problems. [9]
I would change one condition at a time and save unsaved input first. Repeatedly resetting a browser during a confirmed server incident adds little clarity.
In a business network, the responsible IT team should handle checks. OpenAI explains that some features use secure WebSocket connections and may stall if those connections are blocked or interrupted. The answer is not to disable firewalls and protection indiscriminately, but to check required connections in a controlled way. [11]
Do not blindly repeat every action after an interruption
Repeating a plain text response is usually manageable. For an agent task involving file changes or external actions, I would first establish what already happened.
Was a file created? Was a change saved? Has a connected application already accepted an operation?
Only then would I issue a continuation request. Otherwise, an interrupted display could result in duplicate execution. Important operations need clear rules about which steps require explicit approval before being repeated.
Report recurring problems clearly
A useful support report includes the date and time with time zone, interface, model, affected feature and exact error message, alongside comparison checks already completed. OpenAI explicitly requests diagnostic details in its support guidance. [12]
Screenshots should exclude unnecessary customer data or access information. Diagnostic recordings such as HAR files may contain sensitive information and should not be posted unchecked in public forums. Support is available through the Help Center. [12]
For my own assessment, I would also record how long work was actually interrupted and what additional work resulted. That provides a better picture of the impact on a business than an aggregated status display.
What OpenAI says it will improve—and how to judge the result
The incident analyses describe measures including expanding network resources, reducing unnecessary background activity and changing retry behaviour. After the routing incident, OpenAI also discusses staged changes, recovery mechanisms and improved alerting. [2][3][4]
Those explanations matter. Users then need to see whether comparable interruptions are actually prevented.
I would judge reliability through practical questions: Is progress retained? Is a failed task identified clearly? Can it resume in a controlled way? Is a limit distinguishable from a connection problem or provider incident?
Communication matters too. A short acknowledgement is useful initially. Recurring incidents then need an understandable account of the cause and the changes made.
New features are not a substitute for a dependable working environment.
My conclusion: Capability is not enough when work repeatedly stops
The research confirms specific, repeated interruptions to ChatGPT and associated work features. Capacity bottlenecks are among the documented causes, as are configuration and application problems. One explanation for every complaint would be too simplistic.
A precise general increase in error probability cannot be derived from the public information checked. The incidents nevertheless justify taking reliability seriously.
I do not want to reconfigure a tool after every interruption or explain a carefully prepared task from the beginning again. As a platform takes on more work, saved intermediate results and controlled recovery become more important.
ChatGPT's value is not determined only by its best answer. It also depends on whether work can reliably reach that answer.
Context and research
This article reflects the information checked on 12 October 2026. The incidents are a selection, not a complete availability measurement. Cause descriptions come from OpenAI's analyses; individual user reports were not independently investigated. They do not establish an outcome for every account or a particular long-term increase. The author's current observation is identified separately from provider-confirmed incidents. This is general technical information, not an individual technical diagnosis or legal advice.
Sources and further reading
Original sources checked on 12 October 2026. Incident dates do not necessarily describe when the later analysis was published.
[1] OpenAI Status: current status and history
Read source ↗
[1] OpenAI Status: current status and history
Read source ↗
[2] OpenAI: ChatGPT Work seeing elevated errors and latency
Read source ↗
[3] OpenAI: Elevated errors across ChatGPT and Codex
Read source ↗
[4] OpenAI: Elevated errors across ChatGPT, Codex, and the API including the Agents API
Read source ↗
[4] OpenAI: Elevated errors across ChatGPT, Codex, and the API including the Agents API
Read source ↗
[5] OpenAI: incidents affecting paid ChatGPT plans
Read source ↗
[5] OpenAI: incidents affecting paid ChatGPT plans
Read source ↗
[5] OpenAI: incidents affecting paid ChatGPT plans
Read source ↗
[6] OpenAI: Unable to create new ChatGPT Work threads in latest version of desktop app
Read source ↗
[7] OpenAI Developer Community: user reports about history and attachments
Read source ↗
[7] OpenAI Developer Community: user reports about history and attachments
Read source ↗
[8] OpenAI Help Center: What is ChatGPT Plus?
Read source ↗
[9] OpenAI Help Center: Troubleshooting ChatGPT Error Messages
Read source ↗
[10] OpenAI API documentation: Error codes
Read source ↗
[11] OpenAI Help Center: Network recommendations for ChatGPT errors on web and apps
Read source ↗
[12] OpenAI Help Center: How can I contact support?
Read source ↗
[13] OpenAI: Delayed Costs data in the Compliance API
Read source ↗