When a job ends in uncertainty
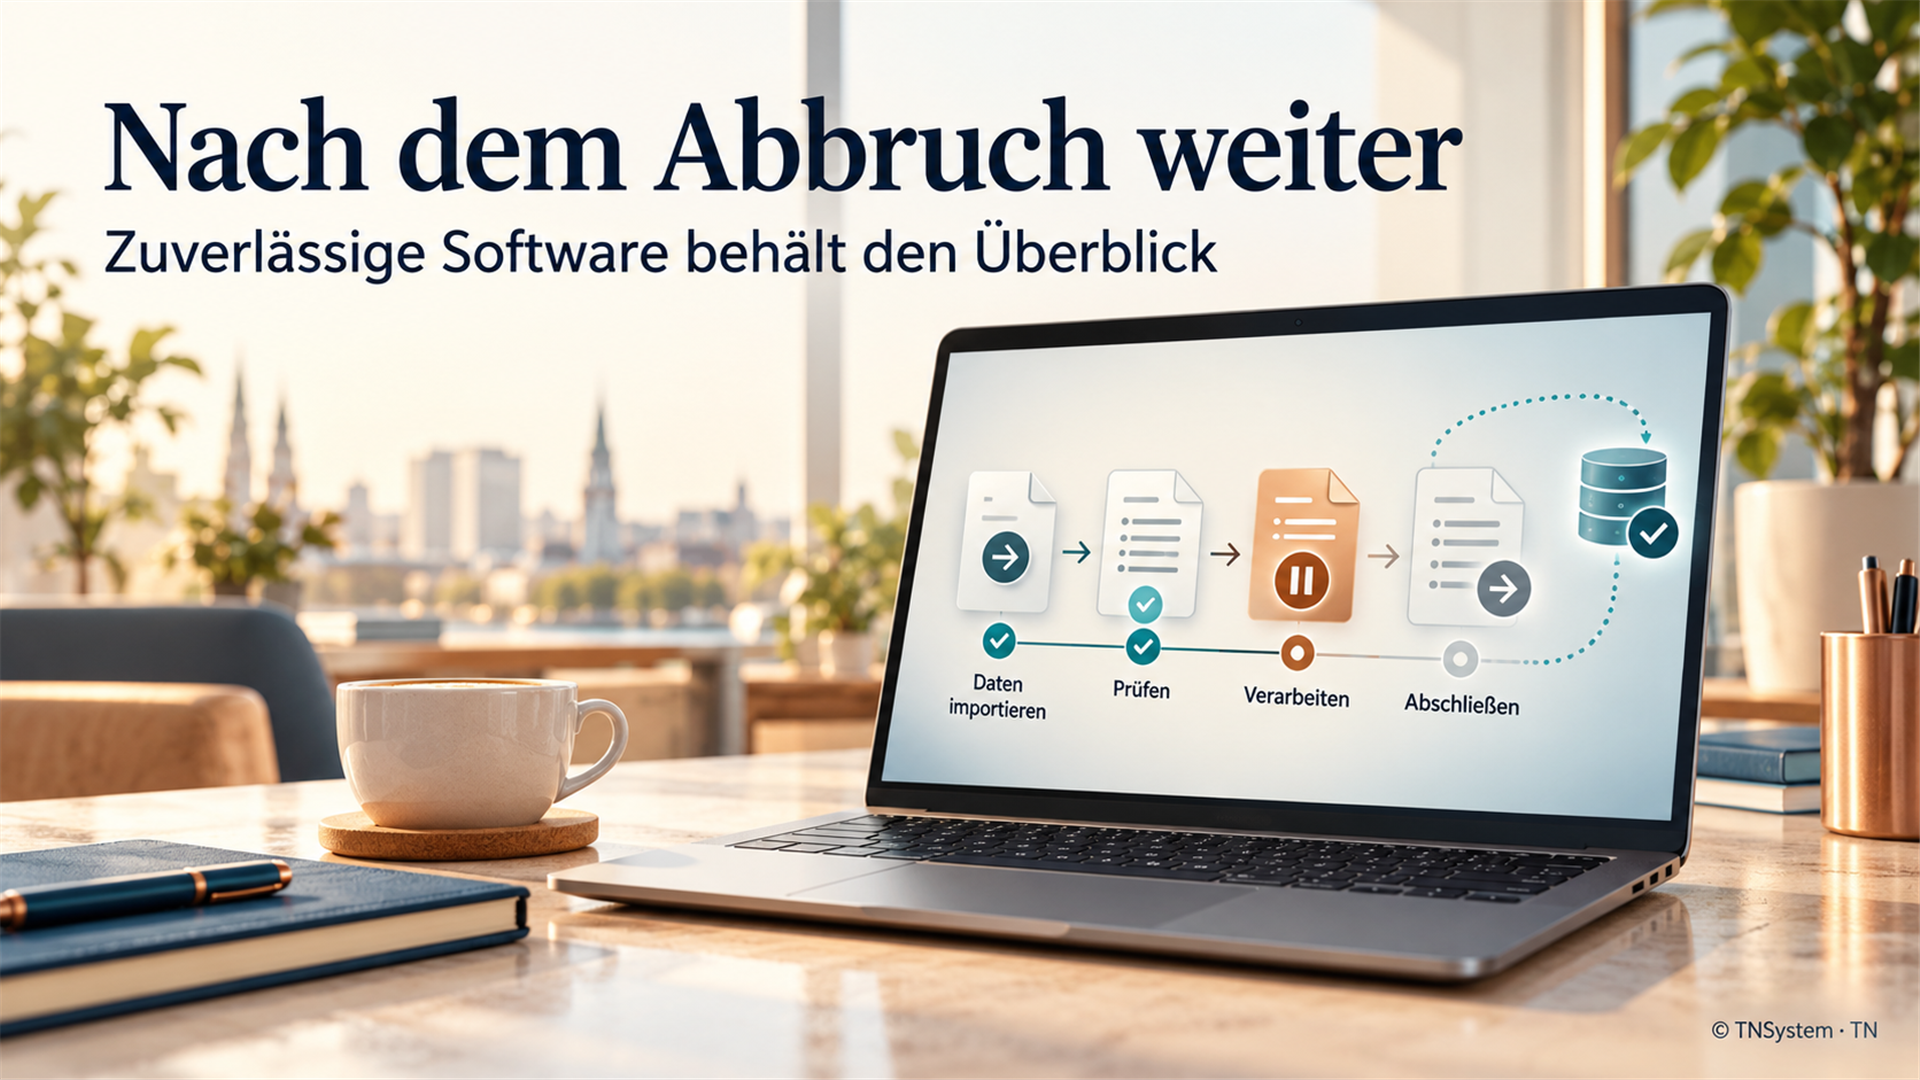
A data import has been running for several minutes when the connection fails. The screen says only “Error”. Have no customer records been imported, have some been saved, or has everything already finished? Clicking Start again needs a firmer basis than hope.
This deliberately simplified example raises an important quality question: does the application know what it has done, or does it leave the person using it to resolve the uncertainty?
The current prompt: persistent workflows
In a practical article published on 12 October 2026, Microsoft discusses when persistent workflows using Durable Task can help. Long-running jobs with interruptions or external approvals are examples. The publication also addresses limitations and unnecessary complexity. [1]
What interests me is less the tool's name than the underlying question: how does an interrupted operation become a traceable job again?
Three states that mean different things
“Accepted” initially means that a job has been registered. “Processing” describes ongoing work. “Completed” should identify a confirmed result. A good interface keeps those states separate.
After a connection failure, I would first show the existing job again. Its identifier, last confirmed step and outstanding work are more useful than an unexplained new Start button. Deliberate pauses need to be clear too: is the job waiting for approval, or has something actually failed?
A retry must not create a second transaction
The difficult case lies between systems. An external service may have performed an action without its response reaching the caller. No response then means neither confirmed success nor confirmed failure.
For those steps, I would design a stable job identifier, reconciliation with the other service and an explicit retry policy. A second request for the same job should not accidentally create a second business transaction. Such safeguards are often discussed under idempotency. Microsoft explicitly distinguishes persistent workflow history from guaranteed exactly-once external effects. [1]
Architecture needs clear boundaries
Persistent workflows may replay orchestration code. Microsoft's documentation therefore requires predictable behaviour and separation of external actions from orchestration. [2]
I would not turn that into a blanket requirement for a framework. A small import may be adequately served by an existing jobs table and a well-designed background process. A complex process involving several approvals may need more support. The solution should fit the problem, not the other way round.
How I would assess the result
A successful uninterrupted run would not satisfy me on its own. I would examine interruptions before processing, during a step and after an externally confirmed action. Afterwards, it should be possible to explain what was saved and how work resumes.
I would also check two almost simultaneous start attempts. Do they remain one job? Does the application detect conflicting inputs? Is the need for manual reconciliation visible when the external state is uncertain? These are assessment questions, not claims about a particular product.
My conclusion
Reliable software cannot prevent every interruption. It can stop an interruption becoming a guessing game. To me, a traceable recovery path belongs to the function itself, not merely to later error handling.
These examples are design proposals, not an executable implementation guide or a guarantee for arbitrary external systems. Permissions, data integrity and business approvals must remain valid when work resumes.
Sources and context
Research date: 23 October 2026. Vendor publications are not independent product tests. Examples and recommendations are identified as such in the article.
[1] Microsoft: Durable Task in the Real World, 12 October 2026
Read source ↗
[2] Microsoft Learn: orchestration and replay constraints
Read source ↗